
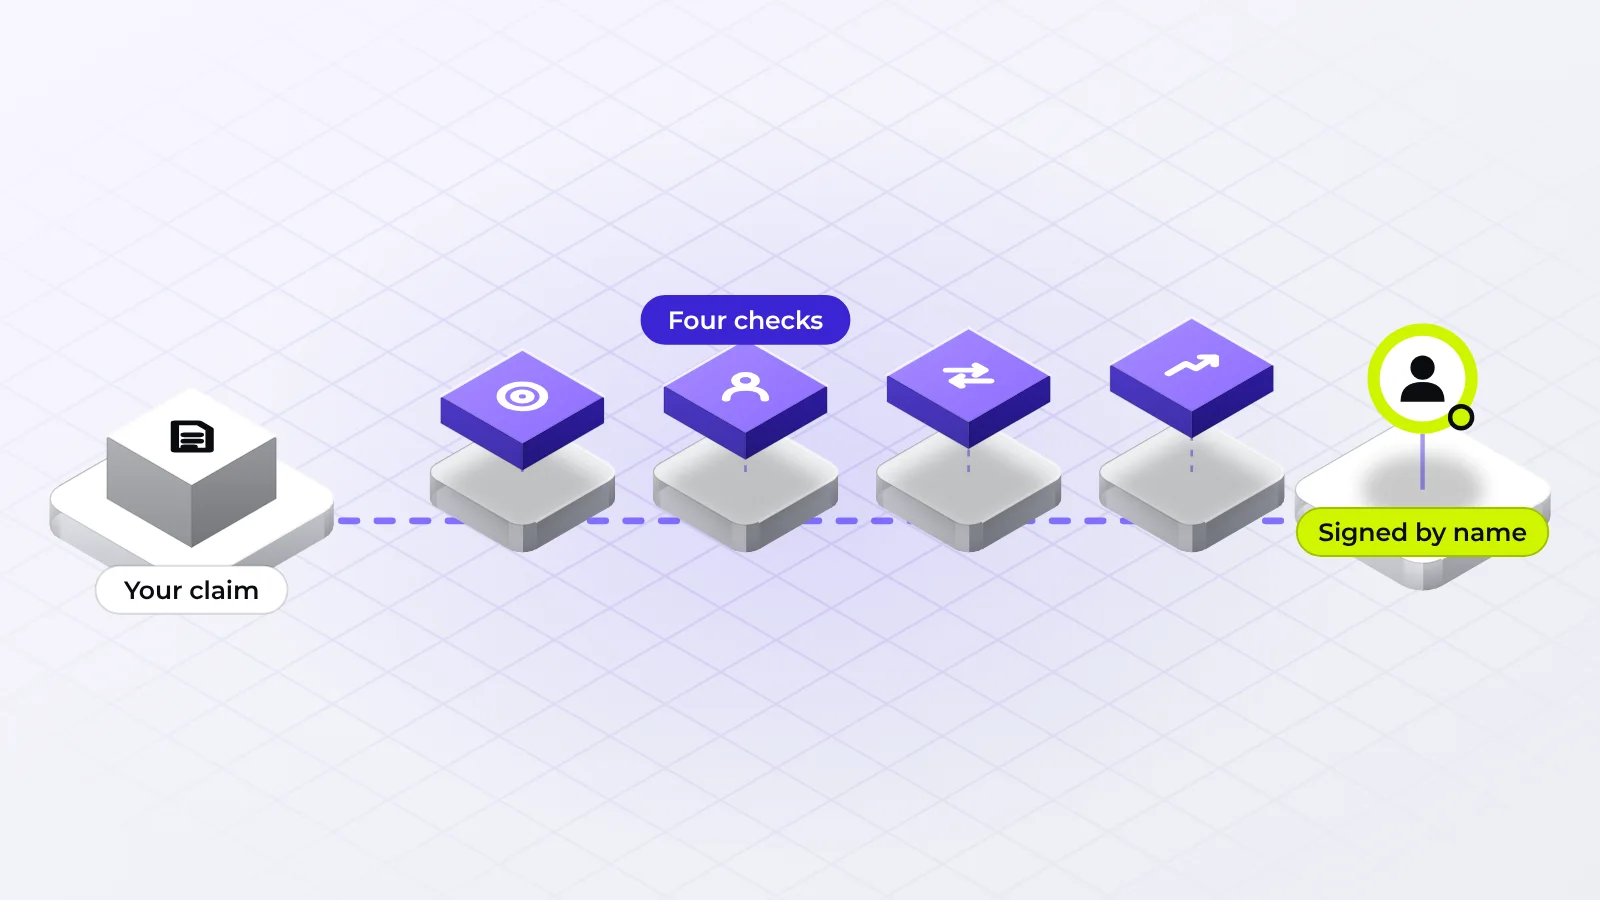
Release Assurance checks every claim in a deck, website or proposal in four steps. Retrieve finds a named, dated source before anyone judges the claim. Challenge tests the claim against the objection a sceptical buyer or investor would raise. Cite attaches the source, an A to E evidence grade and a status. Sign means a named verifier re-checks the high-risk claims and puts their name and the date on the result. This post follows real claims from our anonymised sample report through each step.
What Verified Should Mean
A verified claim is one where someone found the original source, tested it against the strongest objection, wrote down how strong the evidence is, and put their name to the result. Anything less is an opinion about the claim.
The order of those steps matters, and the clearest recent example of getting it backwards is Deloitte's report for the Australian government. In October 2025, Deloitte agreed to repay part of its fee for an A$440,000 report. The Guardian reported that it contained references that didn't exist, including reports attributed to university professors and a made-up reference to a court decision. Deloitte stood by its findings and didn't say AI caused the errors, although the corrected version did disclose that part of the work used a generative AI tool chain.
What I keep coming back to is what Christopher Rudge, the University of Sydney academic who first highlighted the errors, told the Guardian. When the fake references were replaced, several new ones appeared in place of each one.
So what that suggests is that the original claim made in the body of the report wasn’t based on any one particular evidentiary source.
That's the failure a claim check exists to catch. The claim gets written first and the evidence gets found afterwards. Most B2B decks and websites have a few of these.
Most informal checking is a plausibility test. A colleague reads the slide and decides whether it sounds right. That's useful, but the reader doesn't have to find the source, isn't accountable if they're wrong, and is usually on your side. If the colleague is a general-purpose AI assistant, there's a further problem I'll come to below.
We use one house method for every signed deliverable, set out on our methodology page:
- Agree the question.
- Gather named sources.
- Look for evidence against.
- Reach a plain answer.
- Check, sign and deliver.
Release Assurance runs four checks inside that method on every claim in scope. The rest of this post takes them in order.
Step 1: Agree What Is Being Checked
Before anything is researched, the asset is read and every checkable claim is listed. That means numbers, comparisons, first and only statements, customer results, certifications, funding and anything else a buyer or investor would rely on. The scope is confirmed before work starts, so it can't quietly shrink later to meet a deadline.
In our sample, a 12-slide investor deck for a B2B finance automation company, that list came to 24 claims. Here are five of them, which I'll follow through the rest of this post.
| Claim as written | Status and grade | What the check found | Outcome |
|---|---|---|---|
| Trusted by 140 UK mid-market finance teams. | Flagged, B | Billing export shows 96 paying accounts. The 140 includes 44 trial and churned accounts. | Used by 96 UK mid-market finance teams. |
| The only platform with native Xero and Sage sync. | Flagged, B | Two named competitors list both integrations on their own public pages. | Native Xero and Sage sync, live since 2024. |
| Named a Cool Vendor by a leading analyst firm. | Unverifiable, E | No matching entry found, and the client could not supply the report. | Held back until the report is supplied. |
| Cuts month-end close time by 38% (median of six customers). | Verified, B | Median recomputed from six customer logs: 38%, range 22 to 51%. | Keep, with the range next to the median. |
| SOC 2 Type II certified. | Verified, B | Auditor's report seen. Period, scope and opinion match, but the audit period isn't on the slide. | Keep, and add the audit period. |
A single sentence often holds more than one claim. Trusted by 140 UK mid-market finance teams is a customer count, a country, a segment and a function. Each part can be true or false on its own, so each one is checked on its own.
One column needs a word of explanation. The grade rates the evidence the status rests on, not the claim. That's why the two Flagged claims carry a B: authoritative evidence contradicts them.
Step 2: Retrieve the Evidence Before Judging the Claim
Retrieve means finding a live, dated source for the claim before anyone decides whether it's true. If you judge a claim first, you start hunting for evidence that agrees with you, which is what seems to have happened in the Deloitte report.
Primary sources come first:
- Company facts: Companies House holds incorporation dates, officers and filed accounts.
- Authorisation: the FCA Financial Services Register shows whether a firm is authorised for what it says it does.
- Your own results: your own records, such as the billing export, the pilot logs and the auditor's report.
Sources are fetched and timestamped when we check them, so a figure is tested against what the source says on that day. That's how the sample's customer count fell over. The billing export showed 96 paying accounts. The 140 on the slide included 44 trial and churned accounts. The number wasn't made up. It counted accounts that weren't paying, and a diligence call asks for the customer list.
The analyst badge went the other way. No matching entry turned up in the analyst firm's public vendor lists, and the client couldn't supply the report. So the honest status was Unverifiable. When we can't find something, we say so.
Step 3: Challenge the Claim Against the Hardest Objection
Challenge decides whether the evidence holds. Each claim is tested against the objection an investor or a sceptical buyer would actually raise, and against the strongest counter-evidence we can find.
Our free claims self-audit turns this into three hostile readings, and a claim has to survive all three:
- The sceptical buyer or investor. Half of what, measured how, for whom?
- The regulator. Would this hold up if someone complained about it?
- The plain explanation. Is there a more boring reason for the number, like a handful of early customers with unusually messy processes?
The regulator's reading isn't theoretical. Rule 3.7 of the CAP Code, the UK's non-broadcast advertising rulebook, sets the standard:
Before distributing or submitting a marketing communication for publication, marketers must hold documentary evidence to prove claims that consumers are likely to regard as objective and that are capable of objective substantiation.
For marketing aimed at other businesses, the Business Protection from Misleading Marketing Regulations 2008 are blunter still: "Advertising which is misleading is prohibited."
Back to the sample. The only platform with native Xero and Sage sync failed the first reading with one search. Two named competitors list both integrations on their own public pages. A superlative is disproved by one counter-example, and it puts the claims around it in doubt too. The month-end close figure went the other way. It survived all three readings because the six customer logs were there to recompute it.
Step 4: Cite It, Grade It, Tag It
Cite means nothing is marked verified without a named, dated source attached and a grade for how strong that source is. A citation is a package. It names the source so someone else could find it, gives the date, states the method behind any number and says how confident the verifier is.
The grade comes from the same A to E scale we use across every service. It's set by the evidence behind the claim: how many sources, how authoritative, how recent and how much they agree. It never moves up because a claim is repeated.
| Grade | Name | What it means | How it can be used |
|---|---|---|---|
| A | Corroborated | Multiple high-authority, recent, independent sources fully corroborate the claim. | Can carry a decision-critical claim on its own. |
| B | Authoritative | One or two authoritative, recent sources, no significant contradictions. | Strong support. Named and dated in the deliverable. |
| C | Partial | Credible but older than 12 months, or partial coverage, minor contradictions. | Used with the gap stated. Never dressed up as A or B. |
| D | Weak | Weak sources, significant gaps, or major contradictions present. | Directional at best. Flagged wherever it appears. |
| E | Speculation | Speculation only: no retrieved evidence behind the claim. | Named as speculation. Never used as support. |
Each claim also gets one of four statuses:
- Verified: it matches a primary source.
- Supported: it's true, with a source added or the wording tightened.
- Flagged: it's contradicted or overstated, and it comes back rewritten.
- Unverifiable: no evidence was found, so it's held back until someone supplies it.
Each status carries a severity rating, so a footnote gets a lighter pass than a headline number.
Here's how the 24 claims in the sample deck came out.
| Verified | 16 |
|---|---|
| Supported | 5 |
| Flagged | 2 |
| Unverifiable | 1 |
Source: ThriveFinity, sample Release Assurance Pack (anonymised 12-slide investor deck), checked 20 October 2026. Anonymised sample in the real report format. Not a client average. Chart by ThriveFinity.
Three out of 24 doesn't sound like much. But one was the customer count, one was a superlative a buyer could disprove in a minute, and one was an analyst badge nobody could produce. Those are the kind a diligence call goes after early, and a deck tends to be judged by its weakest claim.
Flagged claims don't just get marked red. On the paid tiers they come back rewritten with a citable alternative, ready to paste back. Trusted by 140 became Used by 96. Less impressive, and much harder to attack.
Step 5: A Named Person Signs
Sign means a named verifier puts their name and the date on the result. Every claim in scope is checked and tagged. On top of that, the verifier personally re-checks every decision-critical and high-impact claim before signing. In the sample that was 11 of the 24, and the Assurance Note says which ones and where AI was used.
| Claims checked and tagged | 24 |
|---|---|
| Re-checked personally by the verifier before signing | 11 |
Source: ThriveFinity, sample Release Assurance Pack (anonymised 12-slide investor deck), checked 20 October 2026. Anonymised sample in the real report format. Not a client average. Chart by ThriveFinity.
The verifier is me. You can read who I am and how I work on the verifier page. If I won't sign something, it doesn't ship. When a claim can't be supported at all, we decline it before any work starts, and the refusal goes on a public log of what we won't sign.
Signing also means being accountable afterwards. If you tell us within 30 days that a factual claim in a paid, signed deliverable isn't supported by its cited source, or is an error we should have caught:
- We correct and re-sign it within 5 working days.
- If the correction changes the verdict, we redo the work free.
- If we can't fix it, the fee for that deliverable is refunded or credited.
The terms are in our refund policy, and confirmed errors are corrected in public on our errata page.
Why an AI Assistant Alone Is Not Enough
General-purpose AI assistants are good at finding sources and drafting. They're a weak final check, for two reasons that are now well documented.
The first is sycophancy, a model's tendency to shift towards whatever the user already believes. Anthropic researchers reported in a 2023 paper that "five state-of-the-art AI assistants consistently exhibit sycophancy" across four kinds of task. A 2025 study at the EMNLP conference found that sycophancy intensity correlates with the strength of the user's argument. That study looked at political topics, so it doesn't measure deck reviews directly. The pattern still worries me. A founder who asks my market's worth £2bn, right? has already told the model which answer they want.
In April 2025 it rolled back an update to GPT-4o in ChatGPT, and its explanation said the update "focused too much on short-term feedback". Its announcement on X put it more bluntly, calling the update "overly flattering and agreeable".
The second reason is that assistants can invent sources that look perfectly real, which is the Deloitte problem. Anthropic's own education team puts the two failure modes side by side in this short video, which I'm including because it explains both in plain terms. It starts at the point where hallucination and sycophancy are defined.
So we use AI where it's strong and keep it away from the final call. It speeds up retrieval and drafting. A person reads the sources, tests the reasoning and signs. Every paid deliverable says which steps used AI, as our AI transparency policy sets out. I go further into the sycophancy research in why most AI deck checks skip the hard part.
What Supported Looks Like on a Real Deck
Verified and Flagged are easy to picture. Supported is the status people understand least, and two of the sample's claims show it. Supported means the claim is true, but it needed a source added or the wording tightened.
- The market size: UK B2B finance automation is a £1.4 to 2.1bn market by 2027. Three published estimates sit between those figures, so the range held. The earlier draft had quoted only the top figure, from a vendor-sponsored report. The wording stayed the same and a footnote now names the three reports and their dates. The evidence grade is C.
- The founders' line: Founded in 2021 by two former finance-systems leads. The Companies House incorporation date matched and both earlier roles were confirmed, but finance-systems lead was one public profile's wording and not the other's. The rewrite uses each founder's exact prior job title.
Neither means the deck is bad. Each is an easy question for an investor or buyer to ask, and each is fixable before the meeting. The sample report shows the full source trail for every claim it covers.
Run the Check Yourself First
You can run a rough version of this on your own asset in an afternoon. Pick the five claims you'd least like to defend in a meeting, then for each one:
- Find the original source. Not the article that quoted it, the thing itself.
- Write down the date, the method behind the number and the sample size.
- Give it an honest grade from A to E using the table above.
- Read it as a sceptical buyer, as a regulator and as someone looking for the boring explanation.
- If it fails, rewrite it to what the evidence supports, or take it out.
The self-audit sheet scores this for you in about 15 minutes. My longer guide on fact-checking a sales deck or pitch deck covers decks specifically, and proof claims on B2B websites covers the claims buyers doubt first on a site.
Be honest about the grading. The hardest part of checking your own claims is that you already believe them.
Where ThriveFinity Fits
We sell Release Assurance as fixed-scope claim checking with a named signature. There are three ways in.
- First Signal (free, under an hour): one claim or a positioning check, with the strongest rebuttal and a suggested edit. It's AI-assisted and unsigned, so treat it as a first look.
- Release Assurance Pack (£699 + applicable taxes, 3 business days): one asset, every claim in scope checked and tagged, weak claims rewritten, ranked rebuttals and a signed Assurance Note.
- Release Assurance Suite (£1,749 + applicable taxes, 5 business days): three or more assets, such as a deck, a one-pager and your website, checked against each other so the same claim says the same thing everywhere.
We're not the right choice for everything. We don't give legal or regulatory sign-off, so a financial promotion, a medical claim or a securities disclosure still needs its regulated reviewer. We don't certify projections as outcomes. We check the method behind them. We don't monitor an asset after release, so when it changes, it needs checking again. And if you haven't decided what the asset should say yet, a Decision Brief is the better first step.
If you just want to see which of your claims a careful reader would doubt, start with a free First Signal. It costs nothing and takes under an hour.
❓ Common Questions
What assets can Release Assurance check?
Can you check a claim that might break advertising rules?
Sources
- Krishani Dhanji. Deloitte to pay money back to Albanese government after using AI in $440,000 report. The Guardian, 6 October 2025.
- Committees of Advertising Practice. The CAP Code, section 3: Misleading advertising (rule 3.7). Checked 20 October 2026.
- The Business Protection from Misleading Marketing Regulations 2008, regulation 3. legislation.gov.uk, checked 20 October 2026.
- Companies House. Find and update company information. Checked 20 October 2026.
- Financial Conduct Authority. Financial Services Register. Checked 20 October 2026.
- Mrinank Sharma and colleagues. Towards Understanding Sycophancy in Language Models. arXiv, October 2023.
- Avneet Kaur. Echoes of Agreement: Argument Driven Sycophancy in Large Language Models. Findings of EMNLP 2025, November 2025.
- OpenAI. Sycophancy in GPT-4o: what happened and what we're doing about it. 29 April 2025.
- OpenAI on X. Announcement of the GPT-4o rollback. 30 April 2025.
- Claude (Anthropic). Can you trust what AI tells you? YouTube, 11 August 2026.
- ThriveFinity. Method, prices, accuracy commitment and sample report as published on thrivefinity.uk (/release-assurance, /methodology, /refund-policy and /sample-release-assurance), checked 20 October 2026.